The Deployment Land-Grab: Why Deployment Became AI's Main Event in 2026
Models stopped being the bottleneck
For three years, enterprise AI spending followed a simple assumption: buy access to a better model, and value would follow. The evidence never supported it. RAND's 2024 root-cause study of AI project failure cites estimates that more than 80% of AI projects fail — twice the rate of IT projects that do not involve AI — and traces the causes to the organisation, not the technology: problems misunderstood by leadership, data that was not ready, systems that never embedded into real workflows. Gartner expects the pattern to hold, predicting that over 40% of agentic AI projects will be cancelled by the end of 2027 on escalating costs, unclear business value, and inadequate risk controls.
In spring 2026, the industry's largest vendors accepted that diagnosis in public, with money. In roughly ten weeks, they announced deployment companies, joint ventures, internal engineering organisations, and partner funds whose entire job is to put engineers inside customers until AI systems run in production. Deployment — unglamorous, on-site, accountable deployment — became the main event.
Ten weeks that repriced deployment
The sequence matters, because each move answered the one before it.
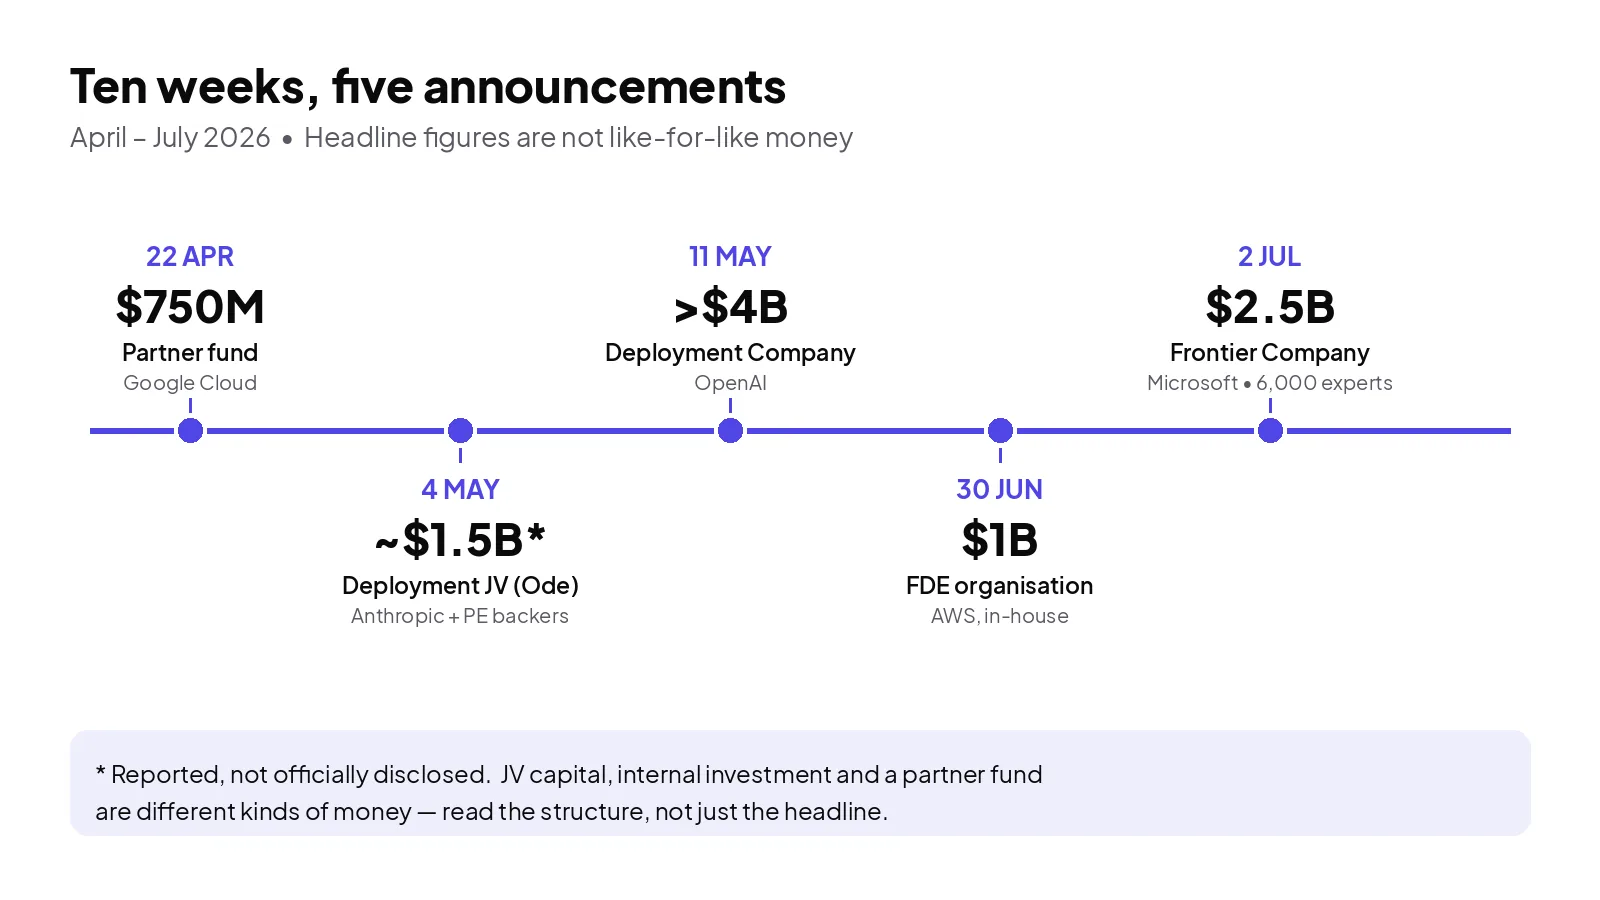
It started at Google Cloud, which announced a $750 million partner fund on 22 April 2026 to support embedded engineering teams across its partner ecosystem. Less than two weeks later, on 4 May, Anthropic launched a deployment joint venture — later unveiled as Ode with Anthropic — built with Blackstone, Hellman & Friedman, and Goldman Sachs among its backers and aimed at mid-market and portfolio companies: a venture reported at roughly $1.5 billion in total capitalisation, a figure reported by the press rather than disclosed in the official announcement.
A week after that, on 11 May, came the largest single move: OpenAI launched the Deployment Company with more than $4 billion of initial investment — majority-owned by OpenAI, backed by nineteen investment firms, consultancies, and systems integrators led by TPG, and absorbing Tomoro, an acquired deployment firm of around 150 specialists, in the process.
The hyperscalers followed. On 30 June, AWS announced a $1 billion forward-deployed engineering organisation — funded internally, organised in pods of about five to six engineers, and aimed at production agentic systems in weeks. Two days later, on 2 July, Microsoft completed the set with Frontier Company, a $2.5 billion deployment company staffed by 6,000 industry and engineering experts — pointedly described by Microsoft's own leadership as going beyond forward deployed engineering, even as it adopted the model in full.
Add the headlines together and you get roughly $9–10 billion. Read them carefully and you get something more useful.
Three kinds of money, three different bets
The figures are not like-for-like, and treating them as one "$9.75 billion bet on FDE" would mislead you:
External joint-venture capital (OpenAI's >$4 billion and Anthropic's reported ~$1.5 billion) is outside money committed to a separate company. Investors expect a return, portfolio companies become a built-in sales channel, and the deployment arm must grow as a business in its own right.
Internal investment (AWS's $1 billion and Microsoft's $2.5 billion) is a vendor funding its own engineers. No outside return is owed — but the engineers work for the vendor, are staffed largely from existing teams, and in one case the spender has not specified whether the money is new or over what period it will be spent.
A partner-ecosystem fund (Google Cloud's $750 million) does not hire a single central army at all. It subsidises deployment capacity across partners — reach and distribution, bought rather than built.
Same headline verb — "deployment" — three different incentives. The structure tells you who the deployment team ultimately answers to: outside investors, the vendor's product roadmap, or an ecosystem quota. That answer matters more than the dollar figure.
Why everyone moved at once
Three pressures converged. First, the pilot evidence above: customers were spending heavily and showing little measurable return, which is a churn risk for every model and cloud contract underneath. Second, scarcity: Indeed's index of forward-deployed engineering postings rose roughly 729% year on year to April 2026, as reported by Business Insider, and Lightcast data reported by Fortune put the median advertised FDE salary above $188,000 — for a role created at Palantir that most vendors had treated as a niche for fifteen years. Vendors who did not build deployment capacity risked watching rivals' engineers become the trusted interface to their own customers. Third, feedback: engineers embedded in production see the failure modes, data problems, and workflow realities that benchmarks never surface, and that field knowledge improves the product. Deployment is not just a service line; it is a sensor network.
In other words, the labs and clouds did not discover a new business in 2026. They admitted where the old one's value was actually being created — and raced to own it.
What the land-grab means if you are buying
A vendor-owned deployment arm brings real advantages: deep knowledge of its own stack, direct escalation into product engineering, and scale. Price those against three questions before you sign:
Stack loyalty. Will this team recommend a rival model when your evals say it performs better on your data — or is every road paved back to the parent stack, cloud, and contract?
Ownership at exit. When the engagement ends, what stays in your building: code in your repo, eval sets, runbooks, and engineers on your team who can run the system — or a dependency you renew?
Whose roadmap wins. In a JV structure, portfolio logic and growth targets are in the room. In an internal structure, the vendor's product priorities are. Neither is disqualifying. Both should be explicit.
An independent, vendor-neutral deployment team exists precisely for the first question: its engineers can select, combine, and replace models against a golden eval set you own, because they owe loyalty to no single stack.
When the land-grab does not help you
Honest limits: none of these announcements puts a system in your production environment next month. Headline capital is not deployed capacity — hiring and training senior deployment engineers is the bottleneck the labour data describes, and a 6,000-person announcement staffed mostly from existing teams is a reorganisation before it is an expansion. A large vendor's deployment arm is also the wrong vehicle if your problem is small, already solved by a standard product, or sits outside that vendor's ecosystem: you will be routed toward the stack regardless of fit. And if your data, evals, and operating knowledge end up owned by the deployment vendor rather than your team, the land being grabbed may be yours.
The model race was about intelligence. The deployment race is about trust, access, and who owns what is learned inside your company. Choose the team whose incentives match yours.
Bring us a problem. If you want a deployment team that works inside your boundary and answers to your evals, start with Trida AI's intake — a few questions, then talk with founders and experts from Trida AI.